> FACT: A language model’s fluent response is no guarantee of accuracy; always verify important names, dates, numbers, and quotes.
# Why Doesn’t a Chatbot ‘Understand’ You? Tokens, Hallucinations, and Context Limits
The sentences appear on the screen so smoothly that it feels like someone is sitting right in front of you. It repeats your name, apologizes, and writes “understood.” Then, in the very next line, it invents a book, flips a date, or cites a law that was never passed. Anger is natural. So is confusion. A machine is not magic. It is a machine designed to attach the next piece. In this article, we will dissect that machine — tokens, next-token prediction, training limits, context windows, attention, and that habit people call hallucination. The focus is straight: why ChatGPT hallucinates — and why any large language model sometimes speaks with absolute confidence while being completely wrong.
This article is not a promotional poster or a boycott banner for any product. It clarifies the distinction between “understanding” and “selecting the most likely next word.” No figures will be fabricated. Only the actual mechanics will be explained.
Why the Machine Feels Like Magic
Humans grasp meaning while conversing. Facial expressions, tone, past disagreements, the room’s atmosphere — everything comes together at once. A chatbot has none of these in their original form. All it has is text, broken down into tiny fragments, and a vast statistical memory of which fragments historically followed such fragments.
When a response arrives in fluent language, the brain triggers the same circuit reserved for a well-educated human. We naturally link fluency with honesty. That is what we learned in school: whoever speaks clearly, knows clearly. Language models unintentionally ride on this exact human vulnerability. Its job is not to “tell the truth,” but to select the “next probable token.” Truth often lies near that probability — but not always.
Even the sentence “understood” stems from that same pattern. In training data, humans wrote “got it” millions of times after a point was made. The model simply repeats that social lubricant. There is no little homunculus sitting inside truly grasping the topic.
What Are Tokens?
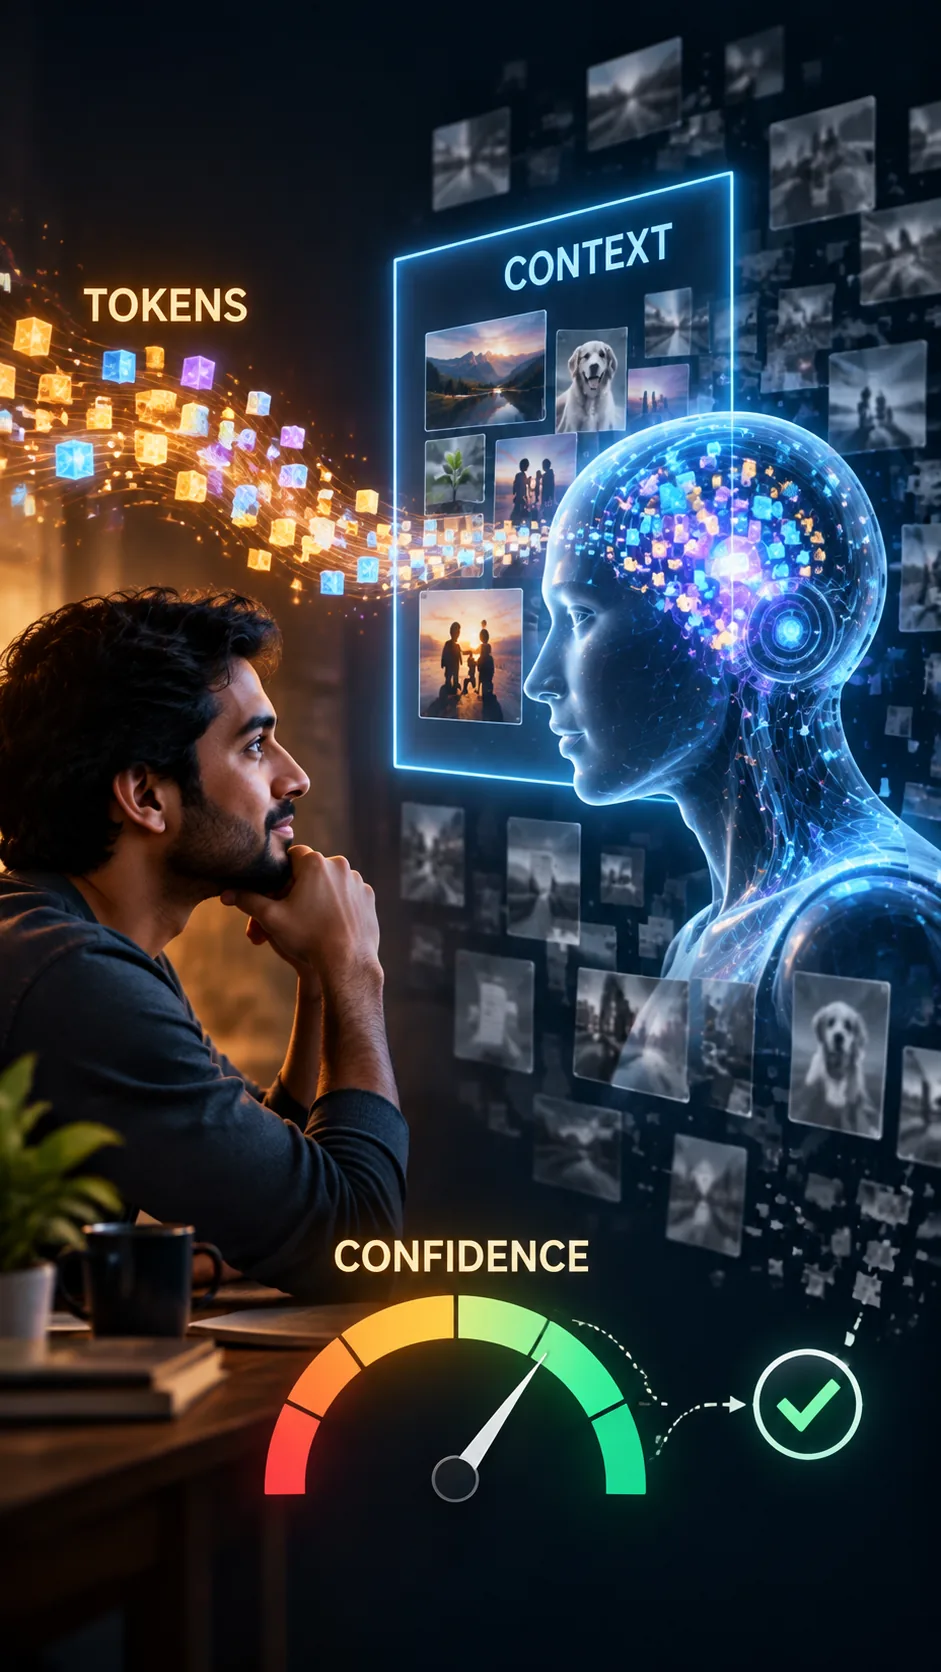
The model does not think letter by letter, nor always word by word. It cuts text into tokens. A token can be a short word, a fragment of a word, a punctuation mark, or a unit including spaces. In English, a token usually centers around a small word or syllable. In Hindi-Devanagari, tokenization cuts can differ because script and sub-word boundaries are different from English.
The long message you send becomes a token queue for the model. The output response is also a token queue, running in reverse — coming out one after another. Therefore, “remembering” often simply means that the fragment is currently inside the window. Anything outside the window ceases to exist for the model at that point, unless maintained by an external memory or re-pasted text.
Token count determines both cost and boundaries. Long PDFs, full chat histories, large blocks of code — all demand a share of the window. Once the window fills up, older parts get truncated. After being cut, the model maintains the exact same confidence because it has no awareness that a page of memory was torn off. Awareness is a human trait, not a property of probability.
Next-Token Prediction — The Real Engine
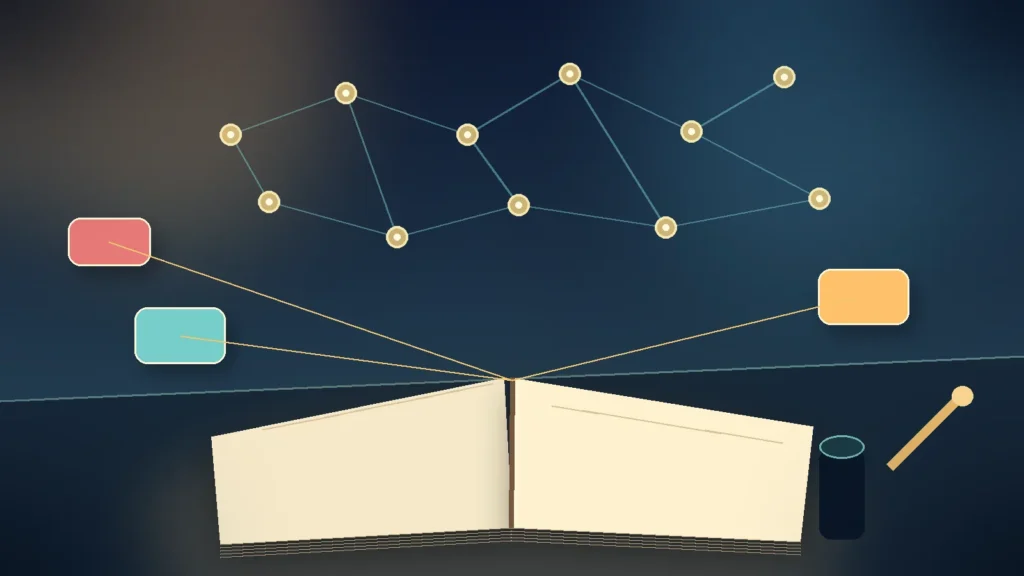
In simple terms, the core job of a large language model is this: based on the tokens received so far, from what distribution should I select the next token? Probabilities are assigned across millions of potential fragments. Then, a fragment is chosen — sometimes the highest probability, sometimes with a touch of randomized flavor (temperature). This new fragment then attaches to the history, and the process repeats.
The entire paragraph does not land after being “thought through” all at once. It is a wall built brick by brick. If the initial brick is slightly slanted, the whole wall can turn out crooked — and the model works to smooth out that very crooked wall, because smooth sentences were rewarded during training.
This is called next-token prediction. The crucial point to understand is that the goal is not to “keep the map of the world accurate,” but to “continue the sequence that feels natural in the data after this sequence.” If there were errors in the data, the pattern of error can also feel natural. If there were two contradictory claims in the data, the model might offer one, then the other, or a mix of both — without ever realizing that the mix is physically impossible.
This is why the model completes your half-written sentences. Incompleteness is just a queue to be extended in the most probable way. A human reads intent in an incomplete sentence. The model does not read intent; it performs statistical continuation.
Training Data and Knowledge Limits
A model does not store the world in its weights like files in a cabinet. It holds statistical relationships. During training, billions of pages, conversations, code, books, and forums turn into token queues to update weights. Information that appeared repeatedly, across multiple sources, in a consistent form becomes stable in output. Information that appeared rarely, contradictorily, or occurred after the cutoff remains weak or missing.
Three limitations are clear here. First: Time. Once weights are frozen, news after that cutoff does not automatically enter the model unless there is fresh training, an update, or an external search tool. Second: Rare facts. Details of an obscure order, local regulation, or private document were either absent or too sparse for weights to build a strong link. Third: Blending. Two true facts existed separately; the model combined them in a single sentence as if they were part of the same event. The combination turned out smooth, but not true.
The word “knowledge” is used carelessly here. Humans bind knowledge with verification, experience, and skepticism. Inside a model’s weights lies a pattern. A pattern often behaves like knowledge — capitals, formulas, idioms. The pattern breaks precisely where the world gets complicated: new events, personal cases, conflicting sources, or questions whose answers were never written in a single sentence in the training data.
Fine-tuning and system instructions can teach style, safety, and brevity. They do not magically install a truth sensor. You can write the instruction “do not guess,” yet the next token can still quietly drift toward guessing, because the full sentence containing the guess looked very appealing during training.
Context Window — The Walls of the Room
Every chat is a room with walls made of tokens. This room is called the context window. System instructions, your past messages, the model’s past answers, attached files — all sit inside this room. If the room is large, a long conversation stays intact. Yet, the room is not infinite.
A point made in the morning outside those walls cannot exist in the afternoon window. The model might still write “as you mentioned earlier” — this phrase is a social habit, not proof of memory. In a long chat, initial facts get buried, mid-way corrections get lost, and the latest message carries the most weight. The user assumes the chat is a single mind. The system assumes: next token for this queue.
File uploads also demand space in the window. You upload an entire novel, the model summarizes it, and then gets a sentence on page 214 wrong — it is possible that page didn’t remain in token form within the queue, or attention assigned it lower weight. “Having read it” does not mean human reading.
Attention and Recency Bias
Transformer models operate using attention. At every new step, the model weighs which tokens from the previous queue appear more relevant right now. This mechanism is powerful, but it is not complete memory. In long contexts, some sentences glow while others blur. The latest instructions often grab stronger emphasis — recency bias. The initial condition can get suppressed.
That is why if you first said “official rules only,” and later asked “give an estimate anyway,” the model might lean toward the second prompt. A human views both sentences as a binding contract. Attention constantly shifts weights. When two opposing instructions exist together, a smooth compromise emerges that half-breaks both.
Attention also does not evaluate which sentence is true in the real world. It only checks which token seems statistically connected in this queue. Connection is no guarantee of truth.
Mechanics of Hallucination
Hallucination here is not a ghost from a movie. In practical terms, it means the model generates a description that is fluent, fits the prompt’s structure, but is incorrect or fabricated in fact, source, or logic. Why ChatGPT hallucinates — the answer is not a conspiracy, but the sum of several tracks working together.
First track: The next token chooses a “plausible-sounding sentence” over fact. Court verdict names, paper titles, section numbers — these templates appear frequently in data. Filling a new name into a template is easy. Whether that name is real is not guaranteed.
Second track: Remaining silent due to ignorance was rarely rewarded during training. In human dialogue, incomplete answers create disappointment. The model learned that providing some complete answer looks better. “I don’t know” is a short sentence. A fabricated complete paragraph feels long and satisfying — in the model’s score, not in real-world truth.
Third track: Rare queries. The more unusual the query, the sparser the data. On sparse data, the peak of probability splits across multiple incorrect peaks. The model picks one peak and expands a whole essay on it.
Fourth track: Pressure for internal consistency. An incorrect year slips out in the first line. The subsequent tokens accept that year as truth and build the story forward. The wall is crooked, but the plaster is smooth.
Fifth track: The user’s framing. “Give full paper references,” “cite case laws,” “provide with sources” — these instructions force the model to output source-like strings. The structure of the string looks right, but the content inside is fabricated. Mimicking structure is not verifying content.
Sixth track: Multilingual and mixed facts. Hindi query, English knowledge base, half translation. Units slip — names, sections, cities. Slipping does not necessarily reduce the model’s confidence.
Hallucination is not an intentional lie. Intent is a human word. For the system, it is a high-probability continuation that happened to crash into real-world facts.
Confidence vs. Accuracy
Pauses, transitions, “certainly”, “it is clear” — these tokens in a model’s response also come from probability. Experts in training data often use assertive language. Therefore, confident language carries a higher statistical weight. High confidence language does not mean high accuracy.
Some systems attempt to calculate separate confidence scores. That score can also be the model’s internal probability, not a real-world match. Probability simply states: how natural is this sentence following this queue. Being natural is a completely different matter from being correct.
Humans misread this. Whoever speaks without hesitation is considered knowledgeable. A chatbot minimizes hesitation in its style because hesitant answers look less “complete.” Looking complete is a dangerous kind of beauty.
This is why when caught making a mistake, the model immediately offers an apology and a revised version — yet the new version can also be fabricated. Apologizing is a learned conversational pattern, not a guarantee of correction.
Ambiguity in Prompts
If a question is incomplete, the model fills in the gaps. “Is this legal?” — which state, which date, which party? Filling blank spaces with an average narrative is part of its job. If that average narrative doesn’t match your specific case, you feel cheated. The system didn’t decide to cheat; it simply selected the most standard continuation.
Multiple instructions at once: keep it brief, keep it detailed, cite sources, simple language, legal precision. These instructions clash with each other in the token queue. Attention will weigh one more heavily. The result is often a smooth compromise that compromises every goal by ten percent.
Persona roles also add to the confusion. Writing “You are a lawyer” makes the model adopt legal jargon. Jargon is not expertise. Role prompts change writing style; they do not grant a license, open a courtroom, or assume liability.
Search, Tools, and Verification — Do They Eliminate Hallucinations?
When systems connect with external web search, calculators, code execution, or databases, certain types of errors decrease. Recent events, direct quotes, numerical figures — these can come from a retrieved source rather than weight memory. Still, the chain can break. Search returns flawed results. The model misinterprets a correct result. A source sentence is stripped of context. A tool failed to run, but the model wrote a pretend output — which is another form of hallucination in the tool era.
Retrieval pastes document snippets into the window. If snippets are incomplete, from wrong pages, or weakly tied to the question, the response will smooth over that exact incompleteness. “With sources” can still attach a line outside the source because the habit of continuation remains strong.
Verification remains a human responsibility — especially for names, dates, legal sections, medical dosages, financial calculations, and quotes. Anything that has a record in the world should be cross-checked against that record. Treat opinions as opinions. The model can write both with equal smoothness.
Everyday Impact: Where Mistakes Hurt Most
Health, law, taxes, investments — a fluent mistake here is expensive. School assignments — fabricated quotes get caught. Office policy — the model turns an incomplete chat detail into a rule. Code — a function appears with a convincing name that doesn’t exist in the library.
There are low-risk areas as well: brainstorming ideas, refining language, suggesting structures, drafting outlines. There, the model is a helpful collaborator, not a witness. The difference lies in intent. We demand evidence from a witness. From a collaborator, a draft. Treating a draft as evidence is that same old mistake — confusing fluency with knowledge.
Practical Advice
Divide your prompts and expectations into three buckets while interacting with the machine. First: What can be verified — names, figures, legal sections, links, quotes. Cross-check these with primary sources after receiving the answer. Second: What is structural — outlines, question lists, text polishing. Treat these as aids for independent thinking. Third: Apparent confidence — “definitely”, “it is clear”. Treat these words as stylistic decoration, not proof.
Assign one task per chat. Do not cram ten instructions into a massive wall of text. Repeat essential constraints at the end, because recency pulls attention. When attaching a file, ask which page was used; if no page is cited in the answer, assume the summary might be incomplete.
Reduce the demand for fabricated references. Commands like “give full APA references for five papers” invite source-like strings. A better prompt: “Do not write anything uncertain; state uncertainties in a separate line.” Even then, there is no guarantee. The only guarantee is your verification.
Do not finalize critical decisions — medical, legal, tax, or financial — without a qualified professional and official documentation. A chatbot can be a first draft, never the final signature.
When you catch an error, do not rely entirely on corrections within the same chat thread. The new context queue might build upon the old mistake. Extract the fact, check it externally, and then ask a fresh, short question with clear instructions.
💡 Callout: Treat any sentence that sounds beautiful with initial skepticism. Beauty is the model’s skill; truth is a property of the real world. The two are not tied to the same token.
Teach children and beginners this single sentence: this tool attaches the next word; it does not act as a witness. The tool can be useful. A witness undergoes a different test.
Conclusion
A chatbot doesn’t “understand” you because it lacks a mind capable of understanding — it operates on token queues and next-token prediction. Training offers patterns, not infinite wisdom. The context window limits the room. Attention illuminates a few lines while leaving others in the fog. Hallucination is often a side effect of the very engine that makes sentences sound so human — a smooth continuation of probability when data is thin, instructions conflict, or form overtakes substance. Confident language is not a receipt of accuracy. Tools and search patch a few holes, not all of them. Wisdom lies in taking the machine off the pedestal of magic and placing it on the table as a tool. A tool is sharp. A tool does not take responsibility for its output. That responsibility stays with you.
FAQ
1. Does a chatbot lie intentionally?
No, not in the sense a human lies. It selects the next probable token. Sometimes that selection collides with reality. Do not read drama or intent into it; understand the mechanism.
2. Why does it forget my earlier points in a long chat?
The context window is limited. Older tokens get dropped or faded out in attention. “Forgetting” is not a mental flaw; it is a physical queue limit.
3. Can better prompting eliminate hallucinations completely?
It can reduce them, but not eliminate them completely. Clear scope, instructions like “say you don’t know if uncertain,” and shorter questions help. Rare facts and requests for citations can still trigger fabricated structures.
4. Is the answer guaranteed to be accurate if search or plugins are active?
No. There remains a possibility of incorrect search results, flawed summaries, missed snippets, or pretend tool executions. Always open the primary source.
5. How should I read a fluent AI response?
Treat it as useful for structure and language formatting. Cross-check names, dates, figures, laws, medical details, and quotes with external records. Treat a confident tone merely as stylistic decoration.
*Disclaimer: This is a general technical explanation, not a guarantee for any specific product or professional legal advice. Always verify critical topics with official sources and qualified experts.*
Word count: 2410
Disclaimer: This AI explanation is educational. Independently verify critical facts.